

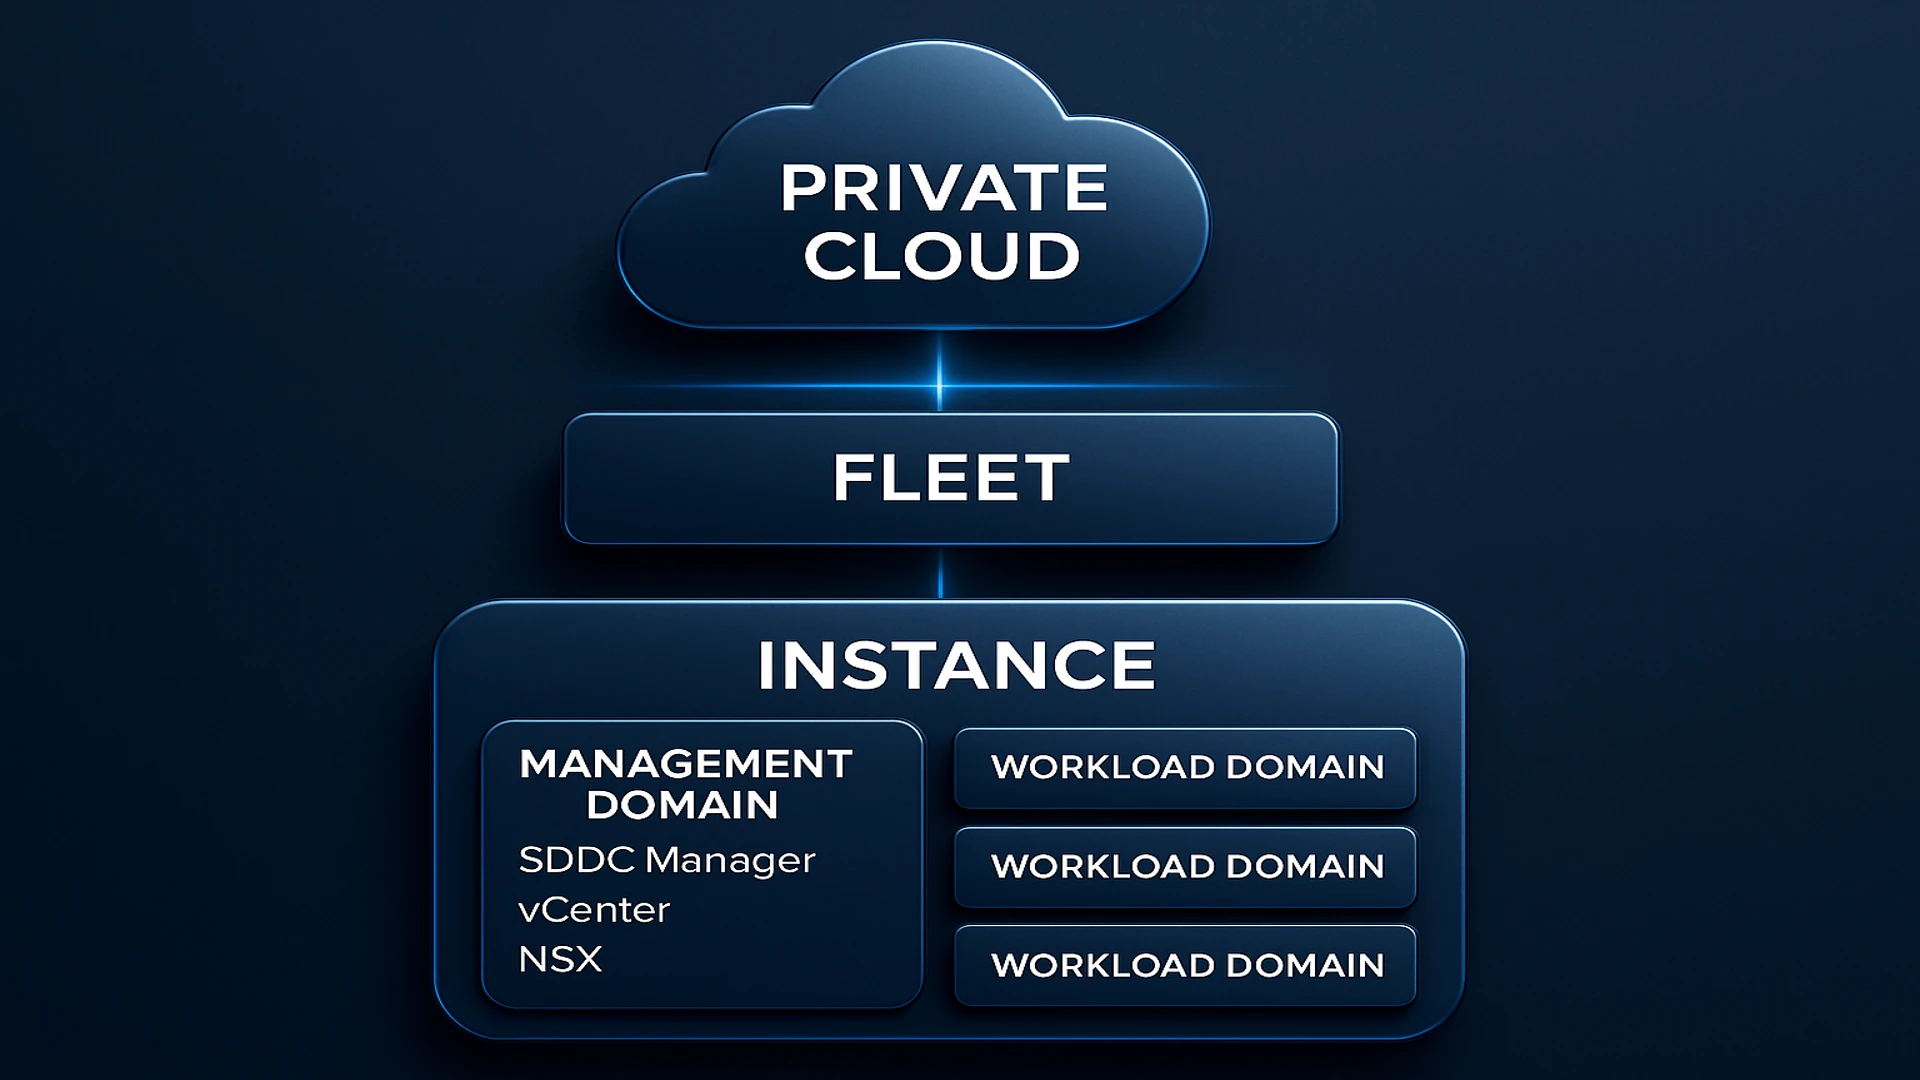
I've been spending more time thinking through how VCF 9 changes the way we talk about architecture, especially around Instances, Fleets, fault domains, and DR.
I wrote up some of my notes here:
 www.vcfinsider.com
The part I keep coming back to is that Site-HA and DR solve two different problems, even though they sometimes get lumped together in the same design discussion. Stretching an environment across fault domains can help you survive a site or AZ failure inside a VCF instance. Once you start talking about losing an entire region, separate VCF instances, recovery orchestration, failback, and everything that comes with that, you're really in a different design space.
I'm curious how people are handling this in production. Are you trying to make one instance as resilient as possible, building separate instances for DR, or using both approaches?
The technology is only part of it. I'm just as interested in what the design looks like six months later when somebody actually has to patch it, test it, fail it over, or explain it to the next engineer.
I wrote up some of my notes here:
VCF 9 Part 1 — Design Considerations: Instances, Fleets, Private Clouds, Fault Domains & DR
A practical primer on VMware Cloud Foundation 9 concepts and deployment patterns—covering instances, fleets, private clouds, fault domains (Site-HA), and cross-region Disaster Recovery.
www.vcfinsider.com
The part I keep coming back to is that Site-HA and DR solve two different problems, even though they sometimes get lumped together in the same design discussion. Stretching an environment across fault domains can help you survive a site or AZ failure inside a VCF instance. Once you start talking about losing an entire region, separate VCF instances, recovery orchestration, failback, and everything that comes with that, you're really in a different design space.
I'm curious how people are handling this in production. Are you trying to make one instance as resilient as possible, building separate instances for DR, or using both approaches?
The technology is only part of it. I'm just as interested in what the design looks like six months later when somebody actually has to patch it, test it, fail it over, or explain it to the next engineer.